About
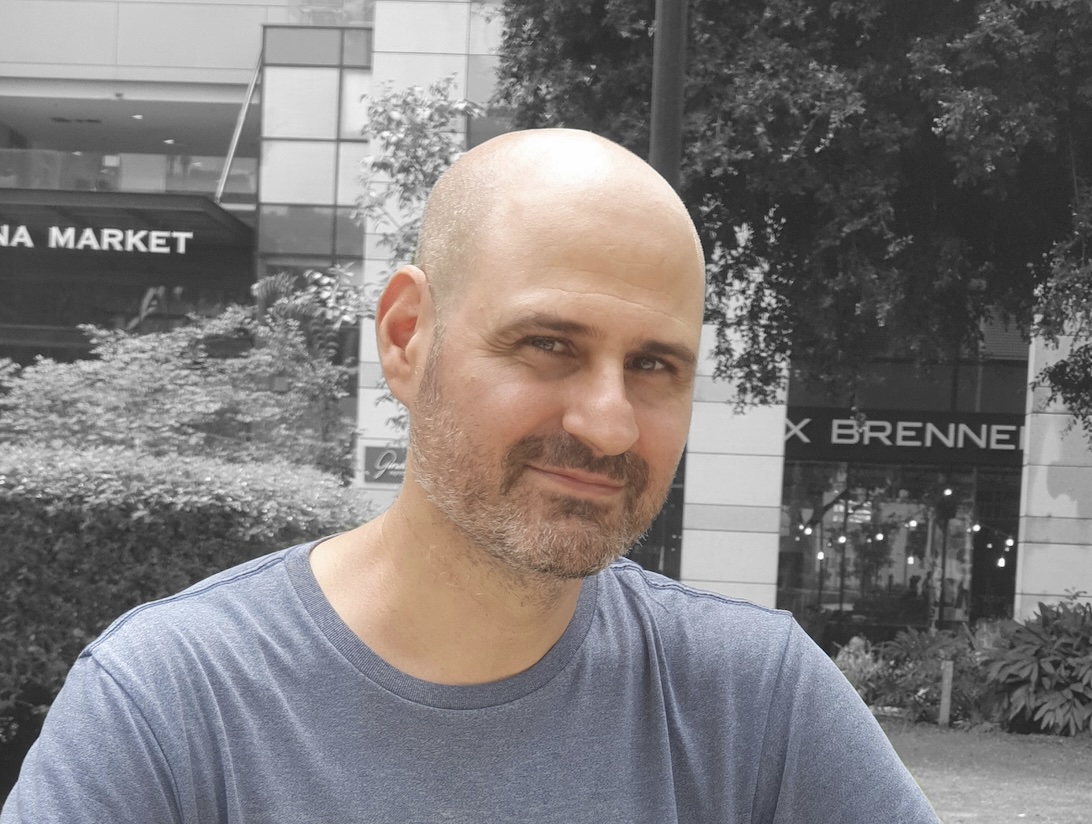
I am a researcher and inventor specializing in data structures and systems.
My work focuses on designing workload-specific data structures and infrastructure systems for storage, indexing, compression, AI infrastructure, blockchain, and memory systems.
I combine a background in data structures theory with broad systems experience across storage, hardware, persistent memory, and large-scale infrastructure.
I led the research, design, and development of ZipNN, a lossless compression algorithm for AI models.
I received my PhD from Tel Aviv University, with a thesis titled “Fewer, Safer Bits: Improved Methods for Massive Storage.”
Selected Work
ZipNN
ZipNN is a lossless compression algorithm for AI models, designed to reduce storage and bandwidth costs at scale without affecting accuracy.
It achieves substantial size reduction, including around 33% on BF16 AI models, while outperforming standard compression approaches in both compression ratio and speed. ZipNN also supports high-throughput operation, reaching decompression speeds of up to 80GB/s.
This work was featured by IBM Research and developed in collaboration with MIT, Boston University, Dartmouth College, and Tel Aviv University.
I led the research, design, and development of the algorithm and its open-source implementation.
Links: ZipNN GitHub | Paper | IBM Research blog
Storage and Indexing
I focus on designing efficient indexing and storage methods for large-scale data systems.
I led the development of elastic indexing techniques (EDBT 2022), enabling dynamic adaptation of index memory usage under varying data workloads while preserving performance.
I contributed to data reduction and storage management techniques (FAST 2019, ACM TOS 2019), including methods for estimating effective storage capacity in deduplicated systems, which were integrated into IBM storage systems.
My more recent work focuses on modern storage architectures, including multi-cloud object storage and cloud bursting (VLDB 2025, with UC Berkeley; HotStorage 2025, with the Technion), with a focus on cost-aware data placement and performance tradeoffs in distributed environments.
Links: EDBT 2022 | FAST 2019 | TOS 2019 | VLDB 2025 | HotStorage 2025
Persistent Memory and Hardware-Aware Systems
My work explores how emerging memory technologies can reshape storage and data systems, from persistent memory to CXL-based architectures.
I contributed to MCAS, a key-value store designed from the ground up for persistent memory, developed using early Intel Optane persistent-memory hardware in collaboration with IBM Research Almaden and academic partners.
Building on this work, I contributed to PyMM, a research library that exposes persistent memory through familiar Python data-science abstractions such as NumPy arrays and PyTorch tensors. The project included an open-source implementation and supported collaborations on persistent-memory acceleration for machine learning and data-intensive workloads.
As the memory landscape moved beyond Optane, my work extended to CXL-based architectures, including cache-line delta techniques for high-frequency VM snapshotting.
My background also includes over a decade of hardware research and ASIC design, with patented work on IP lookup and hardware-based data structures.
This background continues to inform my work across the software-hardware boundary, including storage, compression, AI infrastructure, and emerging memory systems.
Links: MCAS | PyMM paper | PyMM GitHub | CXL Snapshotting
Data Structure Attacks
I co-led research on identifying and exploiting side-channel vulnerabilities in modern data systems, focusing on how internal data structure behavior can leak sensitive information.
In SIGMOD 2023, we showed how row-level security (RLS) mechanisms in relational databases can leak protected data through query execution time, enabling attackers to infer the existence and frequency of hidden data.
In USENIX ATC 2023, we demonstrated “prefix siphoning,” a timing attack on LSM-tree-based key-value stores, exploiting range filters to recover prefixes and, in some cases, full keys.
Links: SIGMOD 2023 | USENIX ATC 2023
Data Structures Theory
My research includes contributions to the theory of data structures, with a focus on indexing and efficient lookup, including predecessor search and longest prefix queries.
This work includes publications in leading theory venues, including Algorithmica and Information and Computation, as well as MFCS, where the work received a Best Paper Award.
Links: MFCS 2013 | Information and Computation 2015 | SWAT 2008 | Algorithmica 2013
Patents
I am an inventor on over 15 patents across several areas, including:
- Storage systems
- Blockchain
- Compression
- Persistent memory
- CXL and disaggregated memory
- Security
- Hardware-based data structures and IP lookup
Selected Talks and Presentations
MIT CSAIL Seminar, Oct 2024 — ZipNN: Lossless Compression for AI Models
Dartmouth College, LISP Lab Seminar, Aug 2024 — ZipNN: Lossless Compression for AI Models
USENIX ATC 2023 — Prefix Siphoning: Exploiting LSM-Tree Range Filters for Information Disclosure [Video]
EDBT 2022 — Elastic Indexing [Video]
Hasso Plattner Institute, Algorithm Engineering Seminar, 2021 — Persistent Memory and Data Systems
Academic Service
General Chair, SYSTOR 2019
Publicity Chair, SYSTOR 2017
Publications
Selected publications are highlighted above. For a complete list, see my Google Scholar profile.